Saturday, May 9, 2015

on rtfm, from a manual reader

Sometimes you're reading and researching online and you get to a post where someone is asking something very basic, or is very misinformed, and a peanut gallery lurker will inevitably step forward and suggest that the poor sap "read the fucking manual", or rtfm.  When this happens, I cheer - manpages are the bedrock of unix; once you've consumed one, you should be 100% competent in the use of that tool.

But sometimes it doesn't work out like it should.  The ip and sudoers manpages are notorious disasters.  (At one point I remember reading an in-depth writeup about what went wrong with the creation of iproute2, but I can't find it now.  If anyone else has the link, please send it to me!)

Despite some gripes I have with the command interface - the primary operations are too dangerous, so there should be no short options - mdadm has a decent manpage.  But today I came across an insane, inscrutable gem:

These same layouts are available for RAID6.  There are also  4  layouts  that  will provide  an  intermediate stage for converting between RAID5 and RAID6.  These provide a layout which is identical to the corresponding RAID5 layout on the first N-1 devices,  and has the 'Q' syndrome (the second 'parity' block used by RAID6) on the last device.  These layouts are: left-symmetric-6, right-symmetric-6, left-asymmetric-6, right-asymmetric-6, and parity-first-6.


What is the "Q" syndrome??  What does it all mean??  Google came up empty.  The world may never know.

Wednesday, May 6, 2015

a lovely chat with the great satan

There are some conversational topics that will make anyone squirm.  Try steering the watercooler talk towards "the big C," or drop "the C word" and watch your friends, family and coworkers' brains begin to shut down.  Yes, I'm talking about Comcast.

About the only thing worse than talking about them is talking to them, but as modern adults we are often burdened with both tasks.  The initial problem that led to my need to contact the big evil Internet machine was one that I don't really heap much blame on them for - they shipped me the wrong thing.

Last week I received a cold call.  The excellent Truecaller told me it was my wonderful ISP - since I give them a load of money each month, it seemed like it might be in my best interest to take the call.

On the phone, I was told that for $3 more a month I could get an Internet connection that was ~4x faster than my current service, plus TV with HBO, plus two cable boxes.  When I asked about shipping and setup fees, I was told that these would be waived, and two cable boxes would be shipped to my house free of charge.  About this I was ambivalent - I'd sort of rather not have TV service in my house, but since it was a requirement to get the faster Internet, I consented, thinking eventually I'd either hook it up or not.

(In my mind, this hard sales push is a direct response to Netflix's recent insane numbers and jubilant CEO.  But maybe they just like fucking with people, I don't really know.)

So the package arrived, large enough for two cable boxes but feeling empty.  Upon opening it up, I found two identical packets of cable TV information, but no cable boxes.  Chalking it up to standard Comcast fuckery, I waited, but the cable boxes never came.  For me, this shipping mixup is somewhat understandable - there's something about putting the right things in the right boxes that can be difficult for people to wrap their heads around.  Not saying that I don't want to put Comcast down as much as possible, but about this I'm not too peeved.

On the suggestion of a coworker, I decided to chat up Comcast online rather than deal with the known nightmare of a phone conversation with them.

But that chat was worse.  In it, Comcast:
  • Transferred me three times to three different departments.
  • Took one to ten minutes to respond after each message.
  • Informed me that I was only slated to receive one cable box.
  • Intimated that I would be charged for the box's delivery no matter what.
  • Informed me that I could not cancel my TV service over the chat system,
  • citing the insecurity of their chat system as the primary reason!
The most fucked up part is, I knew it was a trap when I agreed to the upgrade.  I guess I just wanted to see how much of a trap it was.

After most ISP encounters, people often find themselves in need of a cathartic retelling.  Comcast's depth of unscrupulousness and incompetence is known by all, but it still fairly boggles the mind to see it.  It's sort of like watching a video of a guy doing a backflip, or girl getting hit in the head with a shovel - you aren't surprised that it happened, but does get your sympathetic nervous system pumping.

For the brave, the bored, and the masochistic, the full text of our chat follows.  It took probably an hour from start to finish.  Writing this article took less time than my ineffectual chat.  Enjoy.


Sunday, April 26, 2015

one box to stream them all: installing Kodi on the Fire TV

So I went evil and got a Fire TV.  True, Amazon tries hard to sell you crap at every turn, but the interface is nice, the remote is a dream, and the price is right.  Access to Amazon Prime streaming and Netflix?  Check.  The only thing it's missing is the ability to access local network content.

It turns out it's pretty easy to get Kodi (née XBMC) up and running.

  1. Download adbfire for your platform.  I used WattOS (a Debian-derived Openbox-based desktop Linux distro) and it worked just fine - all dependencies were already installed.
  2. Download the Kodi .apk for Android (ARM version).
  3. Enable "ADB debugging" and "Apps from unknown sources" on the Fire TV.  Get to them in Settings -> System -> Developer Options.
  4. Get the Fire TV's IP from Settings -> System -> About -> Network.
  5. Run adbFire:
    yo@mama $ ./adbFire &

  6. Click the "Device Setup" button at the top, and enter any description and your Fire TV's IP address, and click Save.  You don't need to change any of the other fields.
  7. Click the Connect button.  There will be no progress indicator, but after a few seconds you should see "Device connected" appear in the lower right corner of the screen.
  8. Click the "Install APK" button, and navigate to the Kodi APK file you downloaded in step 2.  The installation process will take a minute or two.
  9. Normally, due to Amazon's evil, you'd have to go deep into the settings to the "Manage all installed applications" menu in order to launch Kodi.  Fortunately, there is a workaround - we hijack an app called "Ikono TV" by installing it and stealing it's entry in the main menu.  So, search for and install "Ikono TV".
  10. In adbfire, click the "Llama options" button.
  11. Make the box look like the screenshot above.  You'll need to change several settings:
    • Check "Install Llama"
    • Tick "Link media center to program"
    • Tick "Replace program icon"
    If you want the Fire TV to launch on startup, then make those choices accordingly.  Click ok when done, and wait the few seconds for the process to complete.  The message about importing via USB is nothing to worry about, you won't need to connect anything to your Fire TV.
  12. On the Fire, go to Settings -> System -> Manage Installed Applications and launch Llama.  Click ok to get through all the first time startup messages.
  13. Navigate to the confused llama icon in the lower left and click it.  Scroll to "Import/Export Data", and choose "Import from USB storage".  I know there's no USB attachments, but this works anyway.  (I'm guessing that adbFire created some sort of virtual USB drive, loaded with the needed llama settings, but I'm not really sure.)  For me, after a few seconds, Llama exited with no message.
  14. Go back to the main menu and launch Ikono TV.  This should stutter for a half second and then actually launch Kodi!  Once you exit, the Ikono TV name and icon should be replaced with those for Kodi!
And you're done!  Don't you sort of feel bad for the Ikono TV developers?  Their app has been hijacked and parasitized by us rogue local content lovers.  Oh well, thanks Ikono TV guys!  And a big thanks to the devs who keep Kodi awesome as well!

Monday, January 19, 2015

make the google domains dyndns work with pfsense

So, it's actually pretty easy.  You already have pfsense set up, and a domain running on Google domains.  Open up the Google domains page and the pfsense page so all informations are readily available.

In the domains list in Google domains, click the DNS icon.  Scroll down to synthetic records, and from the drop down menu choose "Dynamic DNS."

Assuming you're running a single site, you'll want to add entries for the bare URL (mysite.com) and the www subdomain (www.mysite.com).  The bare URL entry should get an "@" sign in the "subdomain" field, and the other should get a "www".

Click the little sideways caret next to the domain name on each entry, and then click the "view credentials" link.  This should reveal the credentials for this subdomain - the username and password.

In pfsense, go to the Services tab and choose Dynamic DNS.  Click the little plus icon to get a new DynDNS entry.

Under "Service type", choose "Custom".  Setup the interfaces according to your network configuration.  In the username field, paste the "username" entry from the Google DynDNS page.  Copy and paste the username and password from the Google DynDNS page into pfsense.

In the Update URL field, paste this: "https://domains.google.com/nic/update?hostname=".  After that, type the name of the domain you are configuring DynDNS for - leave off the "@" for the bare URL version, but be sure to add the "www" or whatever other subdomain.

In the "Result match" field, copy and paste this: "good %IP%|nochg %IP%".  This says that the IP update succeeded if Google's servers responded indicating that there was no change to your client's IP, or if they indicated the change was successful.

For a simple webserver setup, add two entries: one for the base domain ("@" in Google DynDNS) and another for the www prefix.  They both use they exact same setup in pfsense aiside from the small change to the hostname field, but each will have its own set of credentials assigned by Google.

A previous version of this post erroneously instructed users to leave off the subdomain in the hostname field in pfsense.  Updated 1/31/2015 to indicate that the subdomain should be left off for the bare URL, but preserved for "www" and any other subdomain.

Monday, October 27, 2014

getting inside a VM disk image

Have a VM disk image that you need to pull a few files from, but you don't want to spin it up into a VM?  Here's the simplest way I've found to get at the files inside it:

First, convert whatever format it's in to .raw using qemu-img - you'll need a good bit of disk space for this to work.  If your source virtual disk is a qcow2, for example, the command might look like this:

me@box$ qemu-img convert -f qcow2 -O raw var/lib/libvirt/images/own.qcow2 /mnt/thevault/everything/backups/own.raw

Then find the offset of the primary partition inside the image with fdisk:

me@box$ fdisk -l /mnt/thevault/everything/backups/own.raw

Disk /mnt/thevault/everything/backups/own.raw: 21.5 GB, 21474836480 bytes
255 heads, 63 sectors/track, 2610 cylinders, total 41943040 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disk identifier: 0x0008fa87

                                      Device Boot      Start         End      Blocks   Id  System
/mnt/thevault/everything/backups/own.raw1   *        2048    40136703    20067328   83  Linux
/mnt/thevault/everything/backups/own.raw2        40138750    41940991      901121    5  Extended
/mnt/thevault/everything/backups/own.raw5        40138752    41940991      901120   82  Linux swap / Solaris

The partition we are interested in is raw1, the Linux (type 83) partition.  If you installed Debian on the disk and went with standard default partitioning options, putting everything under / in the same partition, yours will be the same.

Pull your unit size from the output as well, which in this case is 512 bytes, and then multiply that by the start sector (2048) to get 1048576.

Now we mount the .img file as a loopback device, starting with our calculated offset:

me@box$ mount -o loop,offset=1048576 /mnt/thevault/everything/backups/own.raw /mnt/own

And now you can access your files inside the old VM disk!  Don't forget to clean up, now.

Wednesday, October 1, 2014

systemd hate - console autologin on Jessie

Quick tip - systemd sucks.

Just kidding, I actually have no opinion on the matter.  I haven't noticed much of a difference yet, except that all the old snippets I find on the internet seem to apply mostly to sysv, and from what I hear, grepping over all of /var/log won't return systemd log results, as they're a binary format.

But I'm a fan of progress, and if systemd fixes some obscure problems deep inside Linux that will eventually bubble up and result in better stuff in my world, then I'm all for it.

The one particular problem I was looking to solve was how to autologin at the console.  Arch's wiki was helpful in this regard.  Unfortunately for me, I failed to realize that Arch and Debian Jessie are different distros, and so when I rebooted to test my console autologin, I instead got a blinking cursor on an empty, unresponsive screen shortly after the kernel messages began their scroll.

After some live booting and poking around, I came to the realization that while agetty is at /usr/bin/ on Arch, it's at /sbin on Debian.  Quick fix, problem solved.

Here's all you have to do to get autologin on Debian Jessie:

root@serv$ mkdir -pv /etc/systemd/system/getty@tty1.service.d/
root@serv$ vi /etc/systemd/system/getty@tty1.service.d/autologin.conf

Then, inside the file type this stuff, substituting $username for the name of the user you want to be automatically logged in:

[Service]
ExecStart=
ExecStart=-/sbin/agetty --autologin $username --noclear %I 38400 linux

If you're actually typing, note the tricky little dash in front of the agetty path, that matters.  Enjoy not having to type two dozen characters the once a year you actually use that physical console on your server!

Tuesday, September 30, 2014

btrfs raid1 as root file system - the immortal life of lil turbo

Sometimes, you just need to reformat.  Instead of trying to convert my existing system from extX to btrfs raid, I reinstalled.  And then converted my brand-new system from ext to btrfs.  Because why do things the easy way when you could do them the hard way?  (If you want to actually convert an existing system, just skip to step 3.  It should work, but this is all cowboy-style, so don't blame me if everything explodes.)  Here are the basic steps.  Be warned, this is from a few weeks old memory:

(If you want to read about how I got here, check this out.  If you just want a guide to do this, the backstory doesn't matter, so just keep reading this page.)
  1. Install Wheezy.  However you normally do; all the defaults are fine.  If you feel like it, you can halve the size of swap and add that back in to the system partition.  Or you can do this later with gparted, or you can leave it and have twice as much disk devoted to swap as the Debian installer thinks you'll need.
  2. Upgrade to Jessie.  Also in the normal way.
  3. root@serv$ vi /etc/apt/sources.list
    :%s/wheezy/jessie/g
    :%s/stable/testing/g
    :%s/^deb-src/#deb-src/g
    :wq
    root@serv$ apt-get update
    root@serv$ apt-get dist-upgrade -y
    
  4. Boot into an alternate Jessie environment.  Or at least something with recent btrfs-tools.  Ubuntu may work, but I made a custom Jessie iso on the Debian live-systems build interface.  This tool is really cool, someone's dedicating a lot of server time to make this thing happen and I think it's awesome.  On the downside, you'll probably have to wait a few days before you make it to the top of the queue, and once your "build finished" email is sent out, you'll have to download the iso in the 24 hours before they delete it.
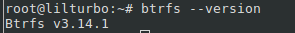
  5. Install btrfs-tools in the live boot.  Once booted into the new environment, we'll need btrfs-tools, of course.  btrfs --version to make sure you've done stuff right - if you're using the ancient Wheezy 0.19 version this stuff may not work right.  The correct version should sound like a kernel version number, mine is currently π:

  6. :)
  7. Convert the just-installed ext root to btrfs.  I got most of my instructions on this step from the occasionally wonderful btrfs wiki.  It doesn't matter if your root is ext3 or ext4 - in fact, these steps may even work with ext2, how should I know.  The steps go something like this:
    root@serv$ # run fdisk -l as root to make sure you're using the hard disk's root filesystem partition for these next steps
    root@serv$ fsck -f /dev/sdX1
    root@serv$ btrfs-convert /dev/sdX1
    
    Use the following optional but prudent steps to make sure your data survived:
    root@serv$ mkdir /btrfs && mount -t btrfs /dev/sdX1 /mnt/btrfs
    root@serv$ btrfs subvol list
    root@serv$ # find the name of the saved subvolume, something like extX_saved
    root@serv$ mkdir /ext_saved && mount -t btrfs -o subvol=extX_saved /dev/sdX1 /ext_saved
    root@serv$ mkdir /orig && mount -o loop,ro /ext_saved/image /orig
    
    Yep, that's a triple mount.  The contents of the last mount should be the same as the contents of your root filesystem.  Check anything important or customized, and, if you're satisfied and want to set everything in stone:
  8. root@serv$ btrfs subvol delete extX_saved
    root@serv$ umount /orig
    root@serv$ rm /ext_saved/image
    root@serv$ umount /btrfs /ext_saved
    root@serv$ rmdir /orig /ext_saved /btrfs
    
  9. Modify fstab. Make sure you change fstab or your system isn't going to boot, fool.  Use blkid to get the UUID of the boot partition and make sure this matches the entry for your / in fstab (I don't think the UUID will change but I can't remember).  Then make sure the line looks something like this:
  10. UUID=deadbeef-beef-dead-beef-deadbeefbeef    /    btrfs    noatime,ssd,discard,space_cache    0    0
    
    Yes, it is correct that btrfs roots get a 0 for passno, the last number - this means don't worry about running fsck, since fsck.btrfs is just a feel-good utility anyway.  They only released it to fit in, the whole story's in the manpage, which is a pretty good read, btw.
    root@serv$ man fsck.btrfs
    
    Anyway, back to stuff that matters - don't just blindly use those mount options in my fstab line - if you use ssd on a drive that isn't an ssd, you'll probably have a bad time.  I didn't turn on certain options like autodefrag and compress=lzo becuase this is intended to be a VM server, and also probably because I don't know what I'm doing.  Check this out, the corresponding page on the ever-helpful wiki.  The whole thing is worth a read, make some damn decisions of your own!
  11. Pop out the alternate boot media and reboot.  Sometimes, when emerging from deeply nested sessions, chroots, or alternate boot environments, don't you feel like Cobb waking at the end of Inception?  Anyway, you should be booted into the newly buttery root of your recently installed system now.
  12. Verify integrity and clean up.  I know that shit's boring, yo, but we're gonna do it anyway.
  13. root@serv$ btrfs subvol delete ext_saved
    root@serv$ # allegedly you can verify with btrfs subvol list -d /, but the manpage for the btrfs-tools version pi on Jessie didn't have this documented
    root@serv$ btrfs fi defrag -r /
    root@serv$ btrfs balance start /
    
  14. Add the secondary drive and partition.  To get the second drive partitioned properly, I simply popped in the second drive and dd'ed the existing disk to the second one.
  15. root@serv$ dd if=/dev/sdSETUPDRIVE of=/dev/sdNEWDRIVE bs=32M # don't fuck this up, mmk?
    
    This will clone our boot, system and swap partitions to the new drive.  For general applications, I recommend halving each swap.  Even though I never had you modify the swap part of fstab, Linux is smart and will find and use all swap partitions attached to the computer.
  16. Convert to raid1 live!  "Fuck it, we're doing it live."  Yeah, computers are pretty cool I guess.  From here.
  17. root@serv$ btrfs fi show # to see which device is mounted as root
    root@serv$ fdisk -l # to see which device will be added to form our raid1 (aka, which one is NOT root)
    root@serv$ btrfs device add /dev/sdNOTBOOT1 /
    root@serv$ btrfs balance start -dconvert=raid1 -mconvert=raid1 -sconvert=raid1 -f /
    The last command complains if you try to convert system blocks to raid1 as well (-sconvert=raid1), which is why we use the -f flag, which has the ominous manpage description "force reducing of metadata integrity".  But there is no information I could find out there regarding this, and I want to support complete failover, so this is what I'm using and it's working ok for now.
  18. And we're done!  Isn't it great?  Hypothetically, one of our drives can fail and we'll still be able to boot!  I think we might be screwed if the boot partition gives us trouble, but I'm not realy sure yet.
As always, the Arch wiki docs are unparalleled, peruse related info here.  I hope it all worked, drop a line below if something didn't, or if something did!