So, it's actually pretty easy. You already have pfsense set up, and a domain running on Google domains. Open up the Google domains page and the pfsense page so all informations are readily available.
In the domains list in Google domains, click the DNS icon. Scroll down to synthetic records, and from the drop down menu choose "Dynamic DNS."
Assuming you're running a single site, you'll want to add entries for the bare URL (mysite.com) and the www subdomain (www.mysite.com). The bare URL entry should get an "@" sign in the "subdomain" field, and the other should get a "www".
Click the little sideways caret next to the domain name on each entry, and then click the "view credentials" link. This should reveal the credentials for this subdomain - the username and password.
In pfsense, go to the Services tab and choose Dynamic DNS. Click the little plus icon to get a new DynDNS entry.
Under "Service type", choose "Custom". Setup the interfaces according to your network configuration. In the username field, paste the "username" entry from the Google DynDNS page. Copy and paste the username and password from the Google DynDNS page into pfsense.
In the Update URL field, paste this: "https://domains.google.com/nic/update?hostname=". After that, type the name of the domain you are configuring DynDNS for - leave off the "@" for the bare URL version, but be sure to add the "www" or whatever other subdomain.
In the "Result match" field, copy and paste this: "good %IP%|nochg %IP%". This says that the IP update succeeded if Google's servers responded indicating that there was no change to your client's IP, or if they indicated the change was successful.
For a simple webserver setup, add two entries: one for the base domain ("@" in Google DynDNS) and another for the www prefix. They both use they exact same setup in pfsense aiside from the small change to the hostname field, but each will have its own set of credentials assigned by Google.
A previous version of this post erroneously instructed users to leave off the subdomain in the hostname field in pfsense. Updated 1/31/2015 to indicate that the subdomain should be left off for the bare URL, but preserved for "www" and any other subdomain.
Monday, January 19, 2015

Monday, October 27, 2014
getting inside a VM disk image
Have a VM disk image that you need to pull a few files from, but you don't want to spin it up into a VM? Here's the simplest way I've found to get at the files inside it:
First, convert whatever format it's in to .raw using qemu-img - you'll need a good bit of disk space for this to work. If your source virtual disk is a qcow2, for example, the command might look like this:
me@box$ qemu-img convert -f qcow2 -O raw var/lib/libvirt/images/own.qcow2 /mnt/thevault/everything/backups/own.raw
Then find the offset of the primary partition inside the image with fdisk:
me@box$ fdisk -l /mnt/thevault/everything/backups/own.raw
Disk /mnt/thevault/everything/backups/own.raw: 21.5 GB, 21474836480 bytes
255 heads, 63 sectors/track, 2610 cylinders, total 41943040 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disk identifier: 0x0008fa87
Device Boot Start End Blocks Id System
/mnt/thevault/everything/backups/own.raw1 * 2048 40136703 20067328 83 Linux
/mnt/thevault/everything/backups/own.raw2 40138750 41940991 901121 5 Extended
/mnt/thevault/everything/backups/own.raw5 40138752 41940991 901120 82 Linux swap / Solaris
The partition we are interested in is raw1, the Linux (type 83) partition. If you installed Debian on the disk and went with standard default partitioning options, putting everything under / in the same partition, yours will be the same.
Pull your unit size from the output as well, which in this case is 512 bytes, and then multiply that by the start sector (2048) to get 1048576.
Now we mount the .img file as a loopback device, starting with our calculated offset:
me@box$ mount -o loop,offset=1048576 /mnt/thevault/everything/backups/own.raw /mnt/own
And now you can access your files inside the old VM disk! Don't forget to clean up, now.
First, convert whatever format it's in to .raw using qemu-img - you'll need a good bit of disk space for this to work. If your source virtual disk is a qcow2, for example, the command might look like this:
me@box$ qemu-img convert -f qcow2 -O raw var/lib/libvirt/images/own.qcow2 /mnt/thevault/everything/backups/own.raw
Then find the offset of the primary partition inside the image with fdisk:
me@box$ fdisk -l /mnt/thevault/everything/backups/own.raw
Disk /mnt/thevault/everything/backups/own.raw: 21.5 GB, 21474836480 bytes
255 heads, 63 sectors/track, 2610 cylinders, total 41943040 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disk identifier: 0x0008fa87
Device Boot Start End Blocks Id System
/mnt/thevault/everything/backups/own.raw1 * 2048 40136703 20067328 83 Linux
/mnt/thevault/everything/backups/own.raw2 40138750 41940991 901121 5 Extended
/mnt/thevault/everything/backups/own.raw5 40138752 41940991 901120 82 Linux swap / Solaris
The partition we are interested in is raw1, the Linux (type 83) partition. If you installed Debian on the disk and went with standard default partitioning options, putting everything under / in the same partition, yours will be the same.
Pull your unit size from the output as well, which in this case is 512 bytes, and then multiply that by the start sector (2048) to get 1048576.
Now we mount the .img file as a loopback device, starting with our calculated offset:
me@box$ mount -o loop,offset=1048576 /mnt/thevault/everything/backups/own.raw /mnt/own
And now you can access your files inside the old VM disk! Don't forget to clean up, now.
Wednesday, October 1, 2014
systemd hate - console autologin on Jessie
Quick tip - systemd sucks.
Just kidding, I actually have no opinion on the matter. I haven't noticed much of a difference yet, except that all the old snippets I find on the internet seem to apply mostly to sysv, and from what I hear, grepping over all of /var/log won't return systemd log results, as they're a binary format.
But I'm a fan of progress, and if systemd fixes some obscure problems deep inside Linux that will eventually bubble up and result in better stuff in my world, then I'm all for it.
The one particular problem I was looking to solve was how to autologin at the console. Arch's wiki was helpful in this regard. Unfortunately for me, I failed to realize that Arch and Debian Jessie are different distros, and so when I rebooted to test my console autologin, I instead got a blinking cursor on an empty, unresponsive screen shortly after the kernel messages began their scroll.
After some live booting and poking around, I came to the realization that while agetty is at /usr/bin/ on Arch, it's at /sbin on Debian. Quick fix, problem solved.
Here's all you have to do to get autologin on Debian Jessie:
Then, inside the file type this stuff, substituting $username for the name of the user you want to be automatically logged in:
If you're actually typing, note the tricky little dash in front of the agetty path, that matters. Enjoy not having to type two dozen characters the once a year you actually use that physical console on your server!
Just kidding, I actually have no opinion on the matter. I haven't noticed much of a difference yet, except that all the old snippets I find on the internet seem to apply mostly to sysv, and from what I hear, grepping over all of /var/log won't return systemd log results, as they're a binary format.
But I'm a fan of progress, and if systemd fixes some obscure problems deep inside Linux that will eventually bubble up and result in better stuff in my world, then I'm all for it.
The one particular problem I was looking to solve was how to autologin at the console. Arch's wiki was helpful in this regard. Unfortunately for me, I failed to realize that Arch and Debian Jessie are different distros, and so when I rebooted to test my console autologin, I instead got a blinking cursor on an empty, unresponsive screen shortly after the kernel messages began their scroll.
After some live booting and poking around, I came to the realization that while agetty is at /usr/bin/ on Arch, it's at /sbin on Debian. Quick fix, problem solved.
Here's all you have to do to get autologin on Debian Jessie:
root@serv$ mkdir -pv /etc/systemd/system/getty@tty1.service.d/
root@serv$ vi /etc/systemd/system/getty@tty1.service.d/autologin.conf
Then, inside the file type this stuff, substituting $username for the name of the user you want to be automatically logged in:
[Service]
ExecStart=
ExecStart=-/sbin/agetty --autologin $username --noclear %I 38400 linux
If you're actually typing, note the tricky little dash in front of the agetty path, that matters. Enjoy not having to type two dozen characters the once a year you actually use that physical console on your server!
Tuesday, September 30, 2014
btrfs raid1 as root file system - the immortal life of lil turbo
Sometimes, you just need to reformat. Instead of trying to convert my existing system from extX to btrfs raid, I reinstalled. And then converted my brand-new system from ext to btrfs. Because why do things the easy way when you could do them the hard way? (If you want to actually convert an existing system, just skip to step 3. It should work, but this is all cowboy-style, so don't blame me if everything explodes.) Here are the basic steps. Be warned, this is from a few weeks old memory:
(If you want to read about how I got here, check this out. If you just want a guide to do this, the backstory doesn't matter, so just keep reading this page.)
(If you want to read about how I got here, check this out. If you just want a guide to do this, the backstory doesn't matter, so just keep reading this page.)
- Install Wheezy. However you normally do; all the defaults are fine. If you feel like it, you can halve the size of swap and add that back in to the system partition. Or you can do this later with gparted, or you can leave it and have twice as much disk devoted to swap as the Debian installer thinks you'll need.
- Upgrade to Jessie. Also in the normal way.
- Boot into an alternate Jessie environment. Or at least something with recent btrfs-tools. Ubuntu may work, but I made a custom Jessie iso on the Debian live-systems build interface. This tool is really cool, someone's dedicating a lot of server time to make this thing happen and I think it's awesome. On the downside, you'll probably have to wait a few days before you make it to the top of the queue, and once your "build finished" email is sent out, you'll have to download the iso in the 24 hours before they delete it.
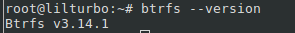
- Install btrfs-tools in the live boot. Once booted into the new environment, we'll need btrfs-tools, of course. btrfs --version to make sure you've done stuff right - if you're using the ancient Wheezy 0.19 version this stuff may not work right. The correct version should sound like a kernel version number, mine is currently π:
- Convert the just-installed ext root to btrfs. I got most of my instructions on this step from the occasionally wonderful btrfs wiki. It doesn't matter if your root is ext3 or ext4 - in fact, these steps may even work with ext2, how should I know. The steps go something like this:
root@serv$ # run fdisk -l as root to make sure you're using the hard disk's root filesystem partition for these next steps root@serv$ fsck -f /dev/sdX1 root@serv$ btrfs-convert /dev/sdX1
Use the following optional but prudent steps to make sure your data survived:
root@serv$ mkdir /btrfs && mount -t btrfs /dev/sdX1 /mnt/btrfs root@serv$ btrfs subvol list root@serv$ # find the name of the saved subvolume, something like extX_saved root@serv$ mkdir /ext_saved && mount -t btrfs -o subvol=extX_saved /dev/sdX1 /ext_saved root@serv$ mkdir /orig && mount -o loop,ro /ext_saved/image /orig
Yep, that's a triple mount. The contents of the last mount should be the same as the contents of your root filesystem. Check anything important or customized, and, if you're satisfied and want to set everything in stone: - Modify fstab. Make sure you change fstab or your system isn't going to boot, fool. Use blkid to get the UUID of the boot partition and make sure this matches the entry for your / in fstab (I don't think the UUID will change but I can't remember). Then make sure the line looks something like this:
- Pop out the alternate boot media and reboot. Sometimes, when emerging from deeply nested sessions, chroots, or alternate boot environments, don't you feel like Cobb waking at the end of Inception? Anyway, you should be booted into the newly buttery root of your recently installed system now.
- Verify integrity and clean up. I know that shit's boring, yo, but we're gonna do it anyway.
- Add the secondary drive and partition. To get the second drive partitioned properly, I simply popped in the second drive and dd'ed the existing disk to the second one.
- Convert to raid1 live! "Fuck it, we're doing it live." Yeah, computers are pretty cool I guess. From here.
- And we're done! Isn't it great? Hypothetically, one of our drives can fail and we'll still be able to boot! I think we might be screwed if the boot partition gives us trouble, but I'm not realy sure yet.
root@serv$ vi /etc/apt/sources.list
:%s/wheezy/jessie/g
:%s/stable/testing/g
:%s/^deb-src/#deb-src/g
:wq
root@serv$ apt-get update
root@serv$ apt-get dist-upgrade -y
:)
root@serv$ btrfs subvol delete extX_saved
root@serv$ umount /orig
root@serv$ rm /ext_saved/image
root@serv$ umount /btrfs /ext_saved
root@serv$ rmdir /orig /ext_saved /btrfs
UUID=deadbeef-beef-dead-beef-deadbeefbeef / btrfs noatime,ssd,discard,space_cache 0 0Yes, it is correct that btrfs roots get a 0 for passno, the last number - this means don't worry about running fsck, since fsck.btrfs is just a feel-good utility anyway. They only released it to fit in, the whole story's in the manpage, which is a pretty good read, btw.
root@serv$ man fsck.btrfsAnyway, back to stuff that matters - don't just blindly use those mount options in my fstab line - if you use ssd on a drive that isn't an ssd, you'll probably have a bad time. I didn't turn on certain options like autodefrag and compress=lzo becuase this is intended to be a VM server, and also probably because I don't know what I'm doing. Check this out, the corresponding page on the ever-helpful wiki. The whole thing is worth a read, make some damn decisions of your own!
root@serv$ btrfs subvol delete ext_saved
root@serv$ # allegedly you can verify with btrfs subvol list -d /, but the manpage for the btrfs-tools version pi on Jessie didn't have this documented
root@serv$ btrfs fi defrag -r /
root@serv$ btrfs balance start /
root@serv$ dd if=/dev/sdSETUPDRIVE of=/dev/sdNEWDRIVE bs=32M # don't fuck this up, mmk?This will clone our boot, system and swap partitions to the new drive. For general applications, I recommend halving each swap. Even though I never had you modify the swap part of fstab, Linux is smart and will find and use all swap partitions attached to the computer.
root@serv$ btrfs fi show # to see which device is mounted as root
root@serv$ fdisk -l # to see which device will be added to form our raid1 (aka, which one is NOT root)
root@serv$ btrfs device add /dev/sdNOTBOOT1 /
root@serv$ btrfs balance start -dconvert=raid1 -mconvert=raid1 -sconvert=raid1 -f /
The last command complains if you try to convert system blocks to raid1 as well (-sconvert=raid1), which is why we use the -f flag, which has the ominous manpage description "force reducing of metadata integrity". But there is no information I could find out there regarding this, and I want to support complete failover, so this is what I'm using and it's working ok for now.
As always, the Arch wiki docs are unparalleled, peruse related info here. I hope it all worked, drop a line below if something didn't, or if something did!
Tuesday, September 9, 2014
on the mortality of SSDs
One of my servers, lil turbo, was booting from one of those bottom-of-the-barrel ADATA 32GB SSDs. There are tons of reviews out there saying that these things are little turds, but I was feeling ballsy. Then, one day, the server wasn't on the network any more. I went into the closet, where lil turbo lives, to see what was the matter.
One of the non-boot drives was locked in a death grip on the sector it had been reading when it was interrupted, and fractured, seemingly non-Latin characters were bleeding all over the display. Fuck.
Rebooted, and no dice. Neither SSD was even seen in POST, not the boot drive and not the one I bought a year ago to mirror the boot drive with.
That was three months ago.
Last week, I decided to take a crack at reviving the comatose lil turbo. Thinking either the SSD hot swap module or the SATA controller had died, I tried replacing both parts. Still no dice.
So I started working on something else, and needed a spare 3.5" HDD to test a bus on a different server (vault 101). So I pulled one of the RAID drives from lil turbo to use. Then, forgetting that lil turbo was missing a drive, I booted it again, and the SSDs showed up! However, they didn't boot - the screen came up with "Missing boot drive" or some shit.
I was thinking that the hot swap enclosure must be loose, and the drive was making connection and then loosing it. But several subsequent boots failed the same way.
Then it hit me. I grabbed the RAID disk back from vault 101 and inserted it in lil turbo's yawning, empty bay, but not all the way. Then I went down the front and opened all the hot swap bays for the RAID disks, nine in all, so none of the would be seen or spun up when I next booted lil turbo.
When lil turbo booted, both SSDs were seen, and once it got to grub, I slowly began closing all the RAID drive bays. Once the system had booted, I issued an mdadm --assemble --verbose /dev/md0 /dev/sd[abcdehijk] and a mount /dev/md0 /mnt/store, and watched the drive lights flicker as my data, marooned for three months, finally came back to me.
Later I learned that the ADATA was a turd after all - the smart log showed two critical-looking errors from around the time that the server would have crashed.
Next step: turn the root into a btrfs RAID1 and mirror it across both drives, finally!
(Edit: So I ended up trying various things live and borked the install. Rather than fixing it or restoring from backup, I decided it was time for a fresh start. Read about how I reinstalled lil turbo to boot from a raid1 btrfs root here.)
One of the non-boot drives was locked in a death grip on the sector it had been reading when it was interrupted, and fractured, seemingly non-Latin characters were bleeding all over the display. Fuck.
Rebooted, and no dice. Neither SSD was even seen in POST, not the boot drive and not the one I bought a year ago to mirror the boot drive with.
That was three months ago.
Last week, I decided to take a crack at reviving the comatose lil turbo. Thinking either the SSD hot swap module or the SATA controller had died, I tried replacing both parts. Still no dice.
So I started working on something else, and needed a spare 3.5" HDD to test a bus on a different server (vault 101). So I pulled one of the RAID drives from lil turbo to use. Then, forgetting that lil turbo was missing a drive, I booted it again, and the SSDs showed up! However, they didn't boot - the screen came up with "Missing boot drive" or some shit.
I was thinking that the hot swap enclosure must be loose, and the drive was making connection and then loosing it. But several subsequent boots failed the same way.
Then it hit me. I grabbed the RAID disk back from vault 101 and inserted it in lil turbo's yawning, empty bay, but not all the way. Then I went down the front and opened all the hot swap bays for the RAID disks, nine in all, so none of the would be seen or spun up when I next booted lil turbo.
When lil turbo booted, both SSDs were seen, and once it got to grub, I slowly began closing all the RAID drive bays. Once the system had booted, I issued an mdadm --assemble --verbose /dev/md0 /dev/sd[abcdehijk] and a mount /dev/md0 /mnt/store, and watched the drive lights flicker as my data, marooned for three months, finally came back to me.
* * *
Later I learned that the ADATA was a turd after all - the smart log showed two critical-looking errors from around the time that the server would have crashed.
Next step: turn the root into a btrfs RAID1 and mirror it across both drives, finally!
(Edit: So I ended up trying various things live and borked the install. Rather than fixing it or restoring from backup, I decided it was time for a fresh start. Read about how I reinstalled lil turbo to boot from a raid1 btrfs root here.)
Tuesday, May 13, 2014
ipv6 is a pain in the ass: fixing openvpn for tmobile
For those of you following along at home, we recently set up an openvpn server and connected our android phone to it. Unfortunately, Big Red doesn't offer unlimited data, and while ovpn doesn't really have too bad of a bandwidth overhead, I decided I'd stop playing chicken with the limited data plan and go to tmobile.
The new phone is a goofy-ass samsung note 3, but I think I like it. Everything went smoothly until I reimported my profile and certificates and tried to connect again - it wouldn't work. Oh shit, does tmobile block VPN? A bit of googling led me to this post. Summarizing: go to Settings -> More Networks -> Mobile Networks -> Access Point Names and change a field in the only apn in the list. But all the fields were greyed out. Do I have to root already?
Nope. The solution is to create another APN, copying in all fields from the first. For your/my convenience, the relevant fields and the values were:
Name: big bob's fun time apn - suck it tmobile!
APN: fast.t-mobile.com
MMSC: http://mms.msg.eng.t-mobile.com/mms/
MCC: 310
MNC: 260
APN type: default,mms,supl
APN protocol: IPv4/IPv6
Roaming APN protocol: IPv4/IPv6
The last two fields are the important ones - "APN protocol" and "Roaming APN protocol". If you don't change the roaming field as well, you won't be able to use vpn when roaming. I don't know what the hell those other fields do, you should use whatever values are in the preset APN on your phone.
The default values are "IPv6 only", but we set up ovpn in tun mode, which does not support IPv6. Change these APN protocol fields to "IPv4/IPv6" and switch to your new and you're golden. Fortunately, the server config, client profile and all certs are still valid.
Yeah, I know IPv4 needs to die, but sometimes we just want our shit to work right and I can't remember a damn IPv6 address other than fe80:: and if you do away with NAT your shit will kind of all be exposed but not really and ...whatever.
The new phone is a goofy-ass samsung note 3, but I think I like it. Everything went smoothly until I reimported my profile and certificates and tried to connect again - it wouldn't work. Oh shit, does tmobile block VPN? A bit of googling led me to this post. Summarizing: go to Settings -> More Networks -> Mobile Networks -> Access Point Names and change a field in the only apn in the list. But all the fields were greyed out. Do I have to root already?
Nope. The solution is to create another APN, copying in all fields from the first. For your/my convenience, the relevant fields and the values were:
Name: big bob's fun time apn - suck it tmobile!
APN: fast.t-mobile.com
MMSC: http://mms.msg.eng.t-mobile.com/mms/
MCC: 310
MNC: 260
APN type: default,mms,supl
APN protocol: IPv4/IPv6
Roaming APN protocol: IPv4/IPv6
The last two fields are the important ones - "APN protocol" and "Roaming APN protocol". If you don't change the roaming field as well, you won't be able to use vpn when roaming. I don't know what the hell those other fields do, you should use whatever values are in the preset APN on your phone.
The default values are "IPv6 only", but we set up ovpn in tun mode, which does not support IPv6. Change these APN protocol fields to "IPv4/IPv6" and switch to your new and you're golden. Fortunately, the server config, client profile and all certs are still valid.
Yeah, I know IPv4 needs to die, but sometimes we just want our shit to work right and I can't remember a damn IPv6 address other than fe80:: and if you do away with NAT your shit will kind of all be exposed but not really and ...whatever.
Friday, May 2, 2014
keeping that data forever (with btrfs)
So we like Linux, that is established. And we must have our data forever, that is also established. But the ability to do this is a new thing. btrfs is a very new thing, allegedly not supported well before kernel 3.9, but with the ability to do some pretty awesome stuff.
If that interests you, read this article. I've read it a few times, and it is absolutely making me drool over the possibilites of btrfs. Failing-ish drives will no longer corrupt files in the mp3 collection you've been curating since high school - an errant cosmic ray can no longer bork that video file from senior week. With anything but zfs and btrfs (even mdadm or hardware raid) this can happen.
So, even though it's probably ill-advised and guaranteed to lose all the data because it's so new, I built a nice shiny new NAS box to test btrfs out on. I'll just be doing backups from other personal machines with it, so if it crashes and burns, the worst that will happen is another device fails catastrophically at the same time and my decades of personal data are all lost. If you use this at your job based solely on these instructions, you're insane. And I like your style.
Start off by installing Debian jessie. Or use wheezy and get the newer kernel from backports, but the newer btrfs-tools in jessie isn't backported. Some of this stuff probably won't work with the older wheezy btrfs-tools.
I bought a couple 3T drives, and I had a couple 1.5T drives laying around, so I figured, why not make it interesting and get another 3T by turning the three spare 1.5T drives into a 3T mdadm raid5? One of the drives was busy elsewhere today, so we're making the array degraded.
Make the filesystem on all three disks, like this:
$ fdisk /dev/sdd
Command (m for help): n
Partition type:
p primary (0 primary, 0 extended, 4 free)
e extended
Select (default p):
Using default response p
Partition number (1-4, default 1):
Using default value 1
First sector (2048-2930277167, default 2048):
Using default value 2048
Last sector, +sectors or +size{K,M,G} (2048-2930277167, default 2930277167):
Using default value 2930277167
Command (m for help): t
Selected partition 1
Hex code (type L to list codes): fd
Changed system type of partition 1 to fd (Linux raid autodetect)
Command (m for help): w
The partition table has been altered!
Calling ioctl() to re-read partition table.
Syncing disks.
Make the mdadm array, make sure it exists and write the mdadm conf file:
$ mdadm --create /dev/md0 --level=5 --raid-devices=3 /dev/sdd1 /dev/sde1 missing
$ cat /proc/mdstat
Personalities : [raid6] [raid5] [raid4]
md0 : active raid5 sde1[1] sdd1[0]
2930012160 blocks super 1.2 level 5, 512k chunk, algorithm 2 [3/2] [UU_]
bitmap: 0/11 pages [0KB], 65536KB chunk
unused devices: <none>
If that interests you, read this article. I've read it a few times, and it is absolutely making me drool over the possibilites of btrfs. Failing-ish drives will no longer corrupt files in the mp3 collection you've been curating since high school - an errant cosmic ray can no longer bork that video file from senior week. With anything but zfs and btrfs (even mdadm or hardware raid) this can happen.
So, even though it's probably ill-advised and guaranteed to lose all the data because it's so new, I built a nice shiny new NAS box to test btrfs out on. I'll just be doing backups from other personal machines with it, so if it crashes and burns, the worst that will happen is another device fails catastrophically at the same time and my decades of personal data are all lost. If you use this at your job based solely on these instructions, you're insane. And I like your style.
Start off by installing Debian jessie. Or use wheezy and get the newer kernel from backports, but the newer btrfs-tools in jessie isn't backported. Some of this stuff probably won't work with the older wheezy btrfs-tools.
I bought a couple 3T drives, and I had a couple 1.5T drives laying around, so I figured, why not make it interesting and get another 3T by turning the three spare 1.5T drives into a 3T mdadm raid5? One of the drives was busy elsewhere today, so we're making the array degraded.
Make the filesystem on all three disks, like this:
$ fdisk /dev/sdd
Command (m for help): n
Partition type:
p primary (0 primary, 0 extended, 4 free)
e extended
Select (default p):
Using default response p
Partition number (1-4, default 1):
Using default value 1
First sector (2048-2930277167, default 2048):
Using default value 2048
Last sector, +sectors or +size{K,M,G} (2048-2930277167, default 2930277167):
Using default value 2930277167
Command (m for help): t
Selected partition 1
Hex code (type L to list codes): fd
Changed system type of partition 1 to fd (Linux raid autodetect)
Command (m for help): w
The partition table has been altered!
Calling ioctl() to re-read partition table.
Syncing disks.
Make the mdadm array, make sure it exists and write the mdadm conf file:
$ mdadm --create /dev/md0 --level=5 --raid-devices=3 /dev/sdd1 /dev/sde1 missing
$ cat /proc/mdstat
Personalities : [raid6] [raid5] [raid4]
md0 : active raid5 sde1[1] sdd1[0]
2930012160 blocks super 1.2 level 5, 512k chunk, algorithm 2 [3/2] [UU_]
bitmap: 0/11 pages [0KB], 65536KB chunk
unused devices: <none>
$ mdadm --examine --scan >> /etc/mdadm/mdadm.conf
Now we make the raid6 btrfs. I used force because some of these disks had already been formatted, but be careful with that option - it doesn't fail mkfs if there is already an fs on the disk.
$ mkfs.btrfs --data raid6 --metadata raid6 --label thevault --format /dev/sd[abfgh] /dev/md0
I stupidly ran the command on the actual physical console so I can't give output, but it looks like the optional features "extref" and "raid56" are turned on by default when you use mkfs.btrfs this way.
Check for your new fs:
$ btrfs filesystem show
Label: 'root' uuid: 810ff954-180f-4997-a487-30c561ff3820
Total devices 1 FS bytes used 1.28GiB
devid 1 size 28.35GiB used 5.04GiB path /dev/sdc1
Label: 'thevault' uuid: 7f407975-6c24-42ec-a9a5-4d1967d89cbe
Total devices 6 FS bytes used 112.00KiB
devid 1 size 2.73TiB used 2.02GiB path /dev/sda
devid 2 size 2.73TiB used 2.00GiB path /dev/sdb
devid 3 size 2.73TiB used 2.00GiB path /dev/sdf
devid 4 size 2.73TiB used 2.00GiB path /dev/sdg
devid 5 size 2.73TiB used 2.00GiB path /dev/sdh
devid 6 size 2.73TiB used 2.00GiB path /dev/md0
Btrfs v3.14.1
There's my boot disk and new storage array! I'm guessing the already-used space is the disk metadata?
Now mount it so we can df it. You can use any component drive as the source of the mount command and btrfs mount will automatically find the other members of the filesystem. I'm using the md block device becuase it's easiest to remember here:
Now mount it so we can df it. You can use any component drive as the source of the mount command and btrfs mount will automatically find the other members of the filesystem. I'm using the md block device becuase it's easiest to remember here:
$ mkdir /mnt/thevault && mount /dev/md0 /mnt/thevault
$ btrfs filesystem df /mnt/thevault
Data, single: total=8.00MiB, used=0.00
Data, RAID6: total=4.00GiB, used=2.00MiB
System, single: total=4.00MiB, used=0.00
System, RAID6: total=10.50MiB, used=16.00KiB
Metadata, single: total=8.00MiB, used=0.00
Metadata, RAID6: total=4.00GiB, used=112.00KiB
We have metadata, outstanding. Regular df appears to work too:
$ df
Filesystem 1K-blocks Used Available Use% Mounted on
/dev/sdc1 29729792 1424256 26350720 6% /
udev 10240 0 10240 0% /dev
tmpfs 828964 416 828548 1% /run
tmpfs 5120 0 5120 0% /run/lock
tmpfs 1964900 0 1964900 0% /run/shm
/dev/sda 17581345080 2176 17572912576 1% /mnt/thevault
So it looks like it works. Time to make some samba shares and copy in a ton of stuff. I'll post back later if there are any problems, or just to mention how it goes after some time has elapsed.
Subscribe to:
Posts (Atom)